About
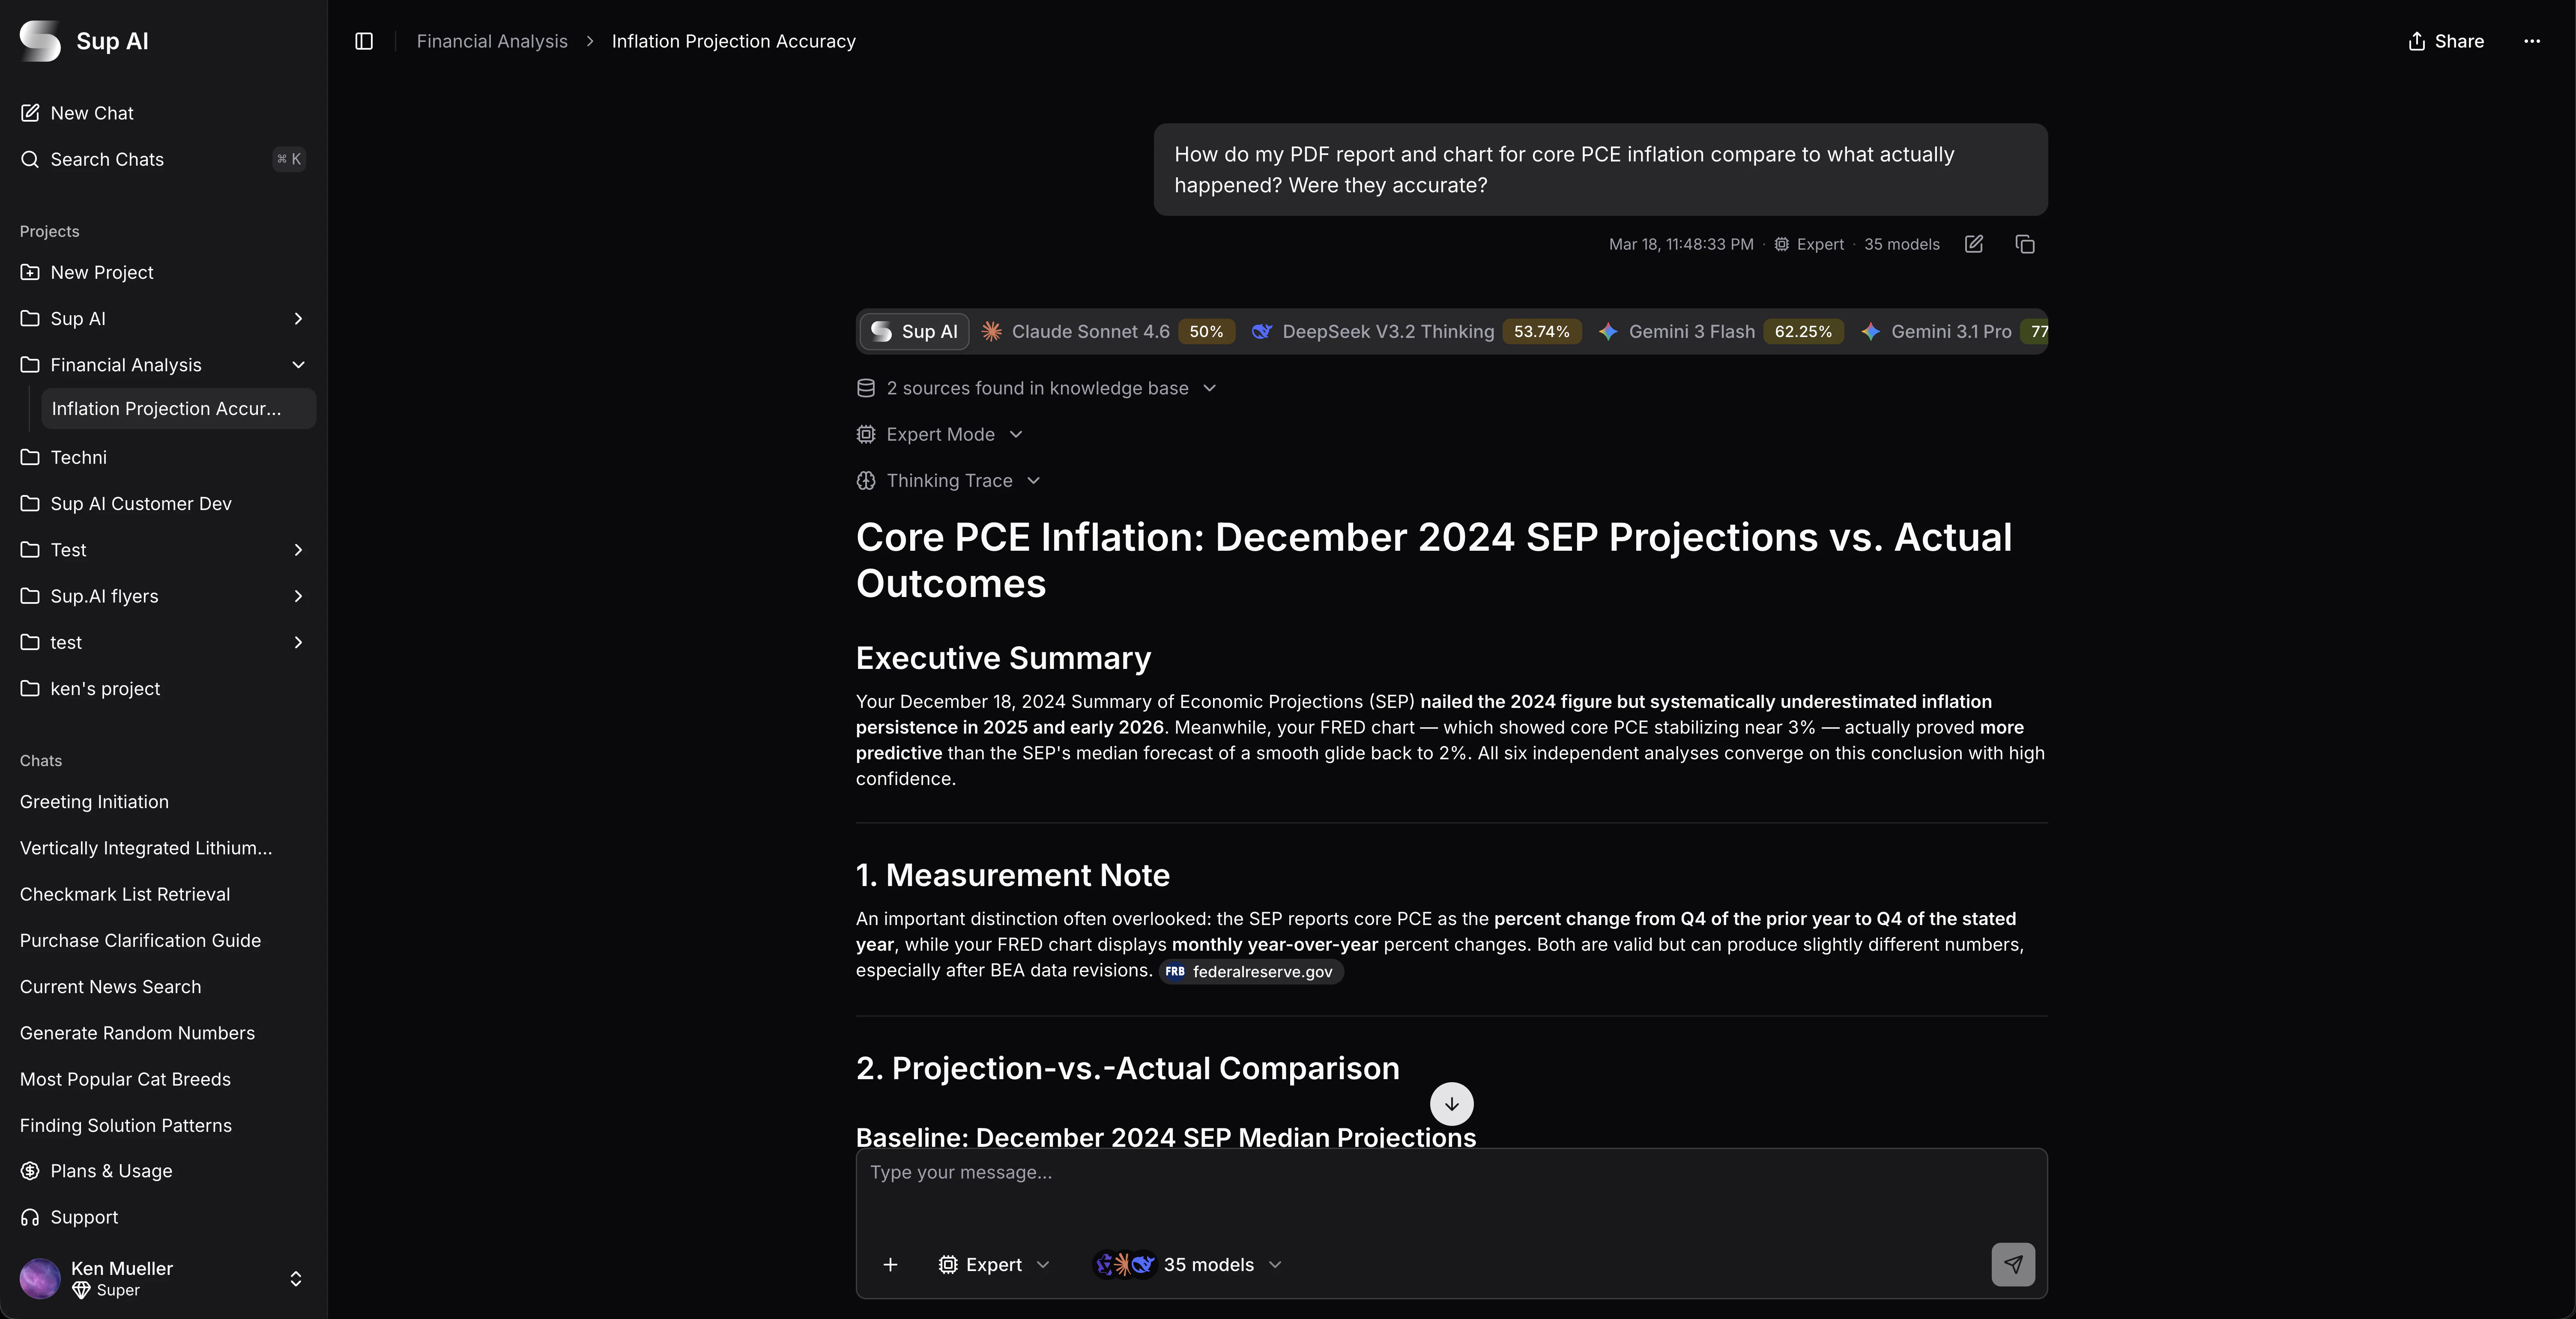
Every LLM hallucinates. They just don't hallucinate the same things. Sup AI runs multiple LLMs (out of 339) in parallel, then synthesizes answers by measuring confidence on every segment. High entropy = likely hallucination, downweighted. Low entropy = likely accurate, amplified. Result: 52.15% on Humanity's Last Exam, 7.41 points ahead of any individual model. $10 starter credit. Card verified. No auto-charge.
Similar & Alternative Tools
Explore popular tools in the same category upvoted by the community.